Internal IT and engineering teams hit a version of this regularly. A migration, an upgrade or a new deployment is scheduled for six weeks. Everyone works flat out. It takes eleven.
The post mortem usually settles on estimation. The estimate was optimistic, lessons learned, next time we’ll add buffer. Then the next project does the same thing.
Estimation is rarely the whole story. The more common explanation is that the team never had the capacity the plan assumed, because a large share of the week was already committed to work nobody counted.
Splitting engineer time between support and projects
The structural problem in most internal teams is that project work and operational work come from the same people and only one of them is scheduled.
Project work has a plan, a deadline and visible tasks. Operational work arrives unannounced: a ticket, an outage, a request from someone senior enough that it jumps the queue, a patch cycle, a vendor escalation, the audit question that takes a day to answer properly.
When planning happens, the team’s capacity is calculated as headcount times available hours, sometimes with a vague allowance for “support”. A support allowance is easy to underestimate when the team has never measured it. If the plan reserves 10 percent for support and the team spends 40 percent on it, the project starts with 30 percentage points less capacity than planned.
There’s a second cost that’s harder to see. Interruption driven work doesn’t just consume its own duration. An engineer pulled off a complex task loses the time plus the cost of getting back into it, which is why a day with four interruptions produces far less than a day with none, even on identical total hours.
Time tracking for development teams, and what to actually measure
The useful measurement here is not total hours. Everyone knows roughly how many hours they worked. It’s the split.
What you want is hours attached to a specific task or project, categorised by type: feature or project work, incident response, support and tickets, maintenance, meetings, code review. A month of data gives you a baseline for the next plan. Set aside time for support, maintenance, meetings, and other recurring work. Then account for planned leave and any projects the team has already committed to.
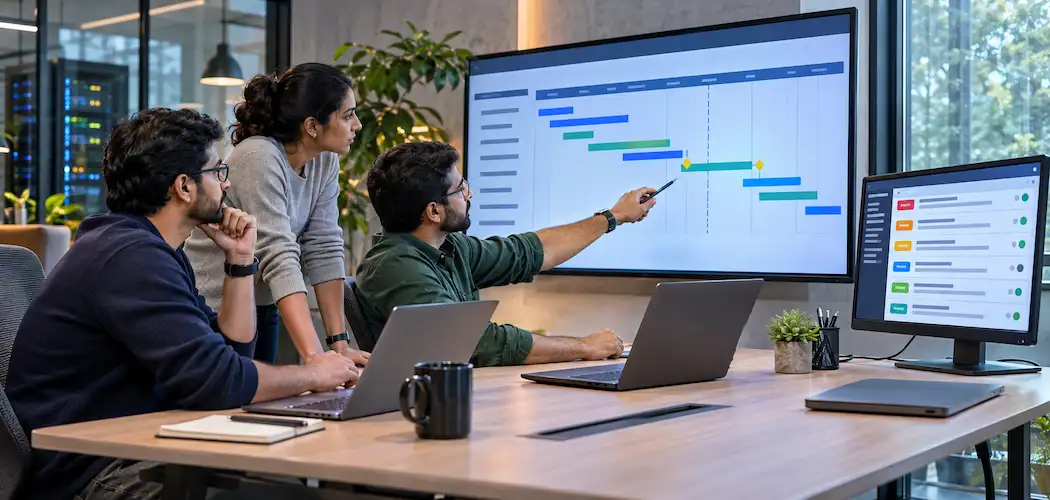
Issue trackers show what work exists and what state it’s in. They generally don’t show what it consumed, which is the gap. Time tracking built for development teams connects logged hours to tasks and projects, updates project budgets and labour costs as hours accumulate, and compares estimated against actual hours by task or project. It sits alongside whatever planning tool you already use rather than replacing it, and it doesn’t produce velocity or burndown charts, which is worth being clear about. It answers a different question: not what the team is delivering, but what the delivery is costing and where the hours went.
The estimated versus actual comparison is where the compounding value is. After a few projects you know which categories of work your team consistently underestimates, which is more actionable than a general instruction to add buffer.
Choosing something the team will actually use
Adoption decides this, not features. Engineers are the group least tolerant of administrative overhead and most capable of quietly ignoring a mandate.
Two practical constraints. Entry has to take seconds, which usually means a short list of active tasks rather than navigating a full project tree. And the data must not be used to compare individuals, because the moment it is, the entries become defensive and the dataset becomes worthless for planning, which was the actual point.
This comparison of time tracking tools for developers and IT teams runs through the main options and what each is suited to. Worth matching the choice to your bottleneck rather than buying the longest feature list, since a tool bought to solve the wrong problem is the standard reason these rollouts die in month two.
Activity monitoring can show when a device was active. Capacity planning needs a different level of detail. A short task entry can show whether that time went to an outage, a support request, or a migration.
A month, then plan differently
Pick one month, log by category, and calculate the proportion of the week that went to unscheduled operational work.
Then plan the next project against the remainder rather than against headcount. Four engineers working 40 hours a week have 960 gross hours over six weeks. If support takes 40 percent, 576 hours remain before accounting for leave, meetings, maintenance, or other commitments outside that support figure.
That single correction removes most of the mystery from projects that slip while everyone is visibly working. The team was never the problem. The arithmetic was.